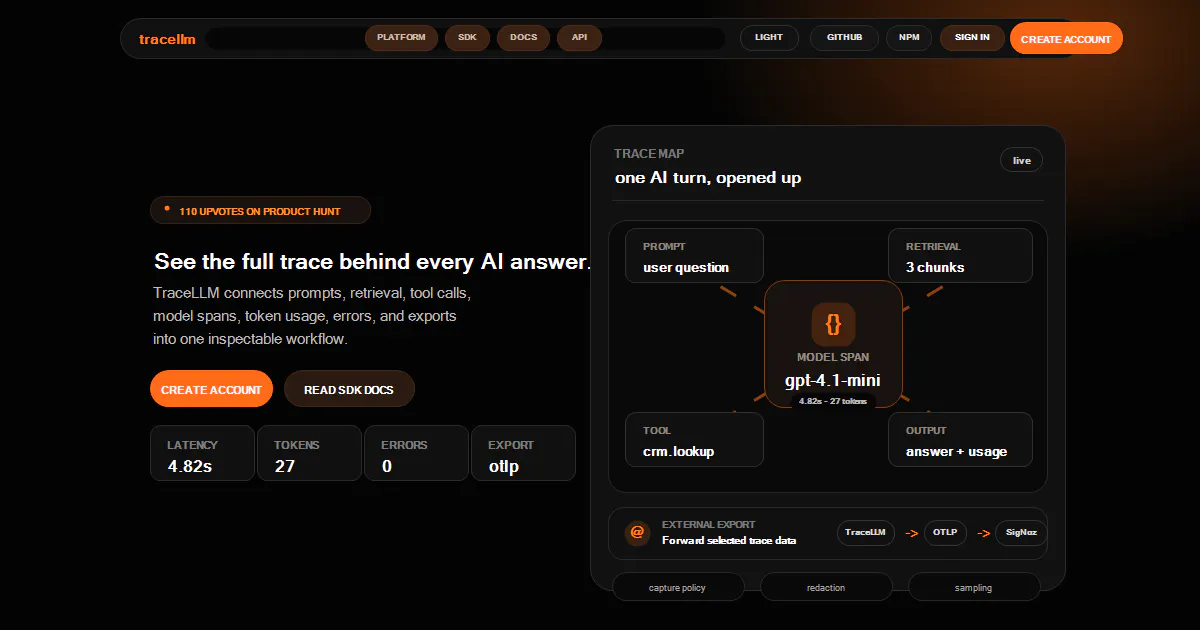
TraceLLM is a specialized observability platform designed explicitly for production AI applications. Developed by Jyotishmoy Deka and launched to the developer community, it provides robust tooling to monitor and optimize LLM workflows in real time.
With TraceLLM, engineering and development teams can seamlessly monitor prompt execution, track token consumption, analyze latency, and evaluate individual spans, errors, and model calls. By leveraging OpenTelemetry (OTLP) to export traces, TraceLLM helps developers quickly pinpoint and isolate performance bottlenecks before they begin to impact end users.
TraceLLM is an observability platform built for production AI applications, allowing developers to monitor prompt execution, token consumption, latency, spans, errors, and model calls.
TraceLLM allows you to export traces using OpenTelemetry (OTLP), making it easier to integrate into standard observability pipelines and identify bottlenecks.
0 community reviews for TraceLLM
Help the community by sharing your experience. Your review helps others make better decisions.

Explorer of Internet